Building a Custom LLM Evaluation Harness in Python from Scratch
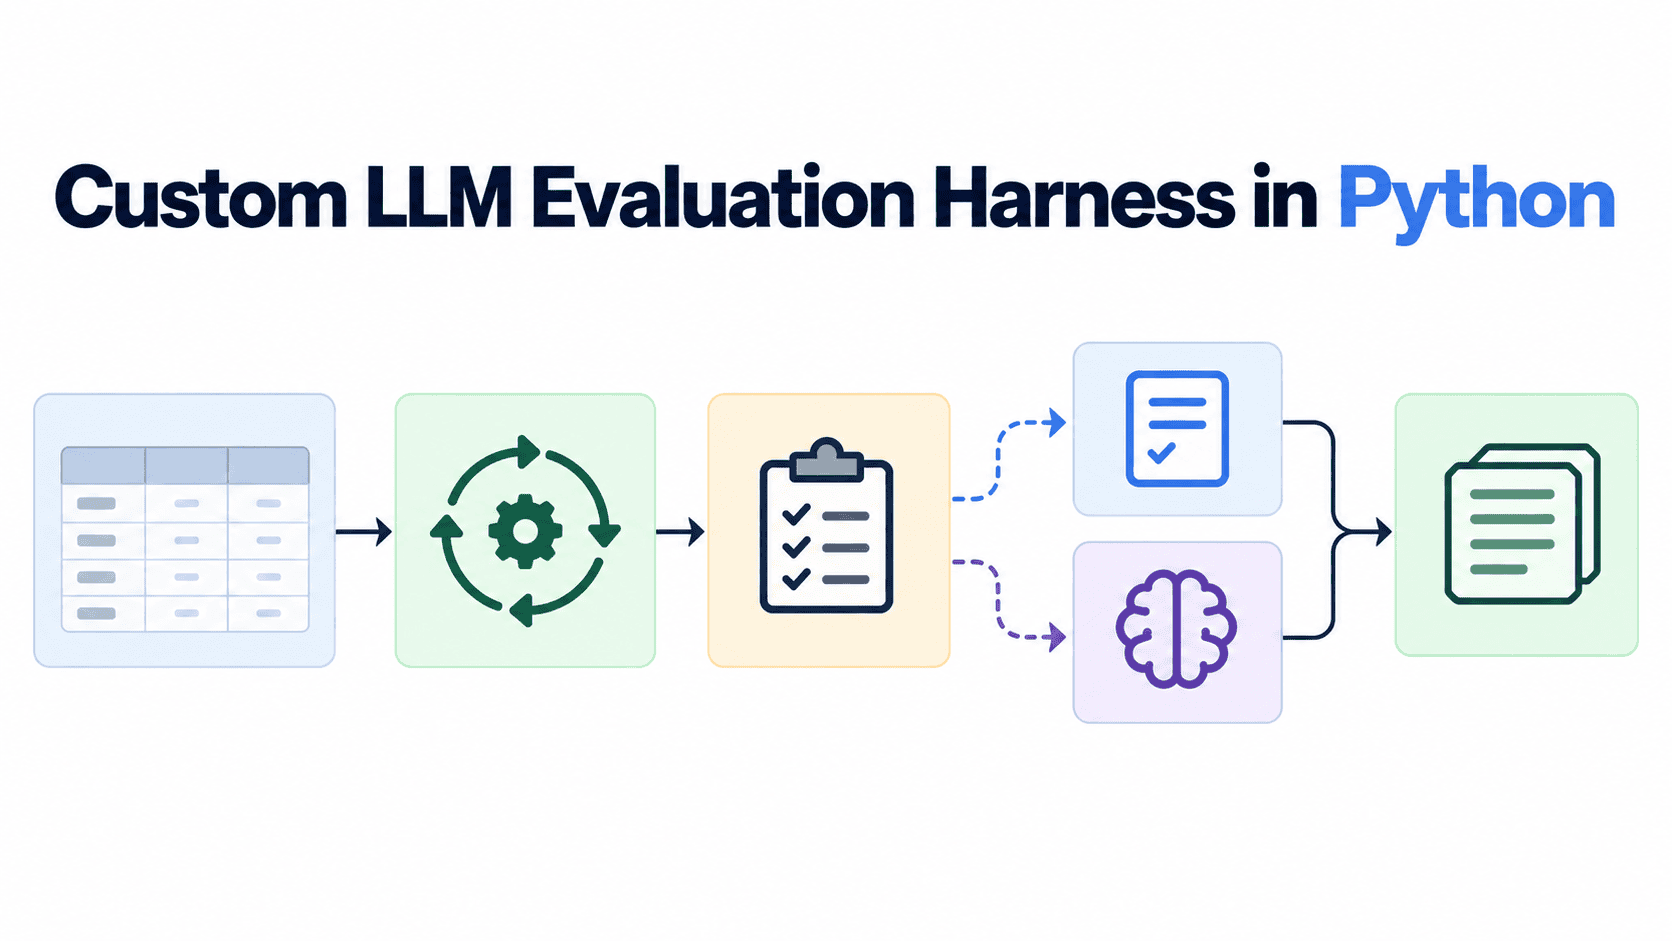
In this article, you will learn how to build a custom LLM evaluation harness in Python from scratch, structured around four modular components that give...
An LLM application can post a higher evaluation score and still become less useful in production. The contradiction is only apparent. An evaluation score is not quality itself, but it is an estimate produced by a particular dataset, metric, judge, sampling strategy, and aggregation rule. If any of those differ from production, optimization can move the score upward while moving actual system behavior in the wrong direction.
Current evaluation guidance explicitly recommends task-specific tests that reflect real-world distributions, production data, continuous evaluation, and calibration against human judgment rather than treating a single numerical score as sufficient.
Discussion (0)
No comments yet. Start the conversation!