Tech
 MarkTechPost
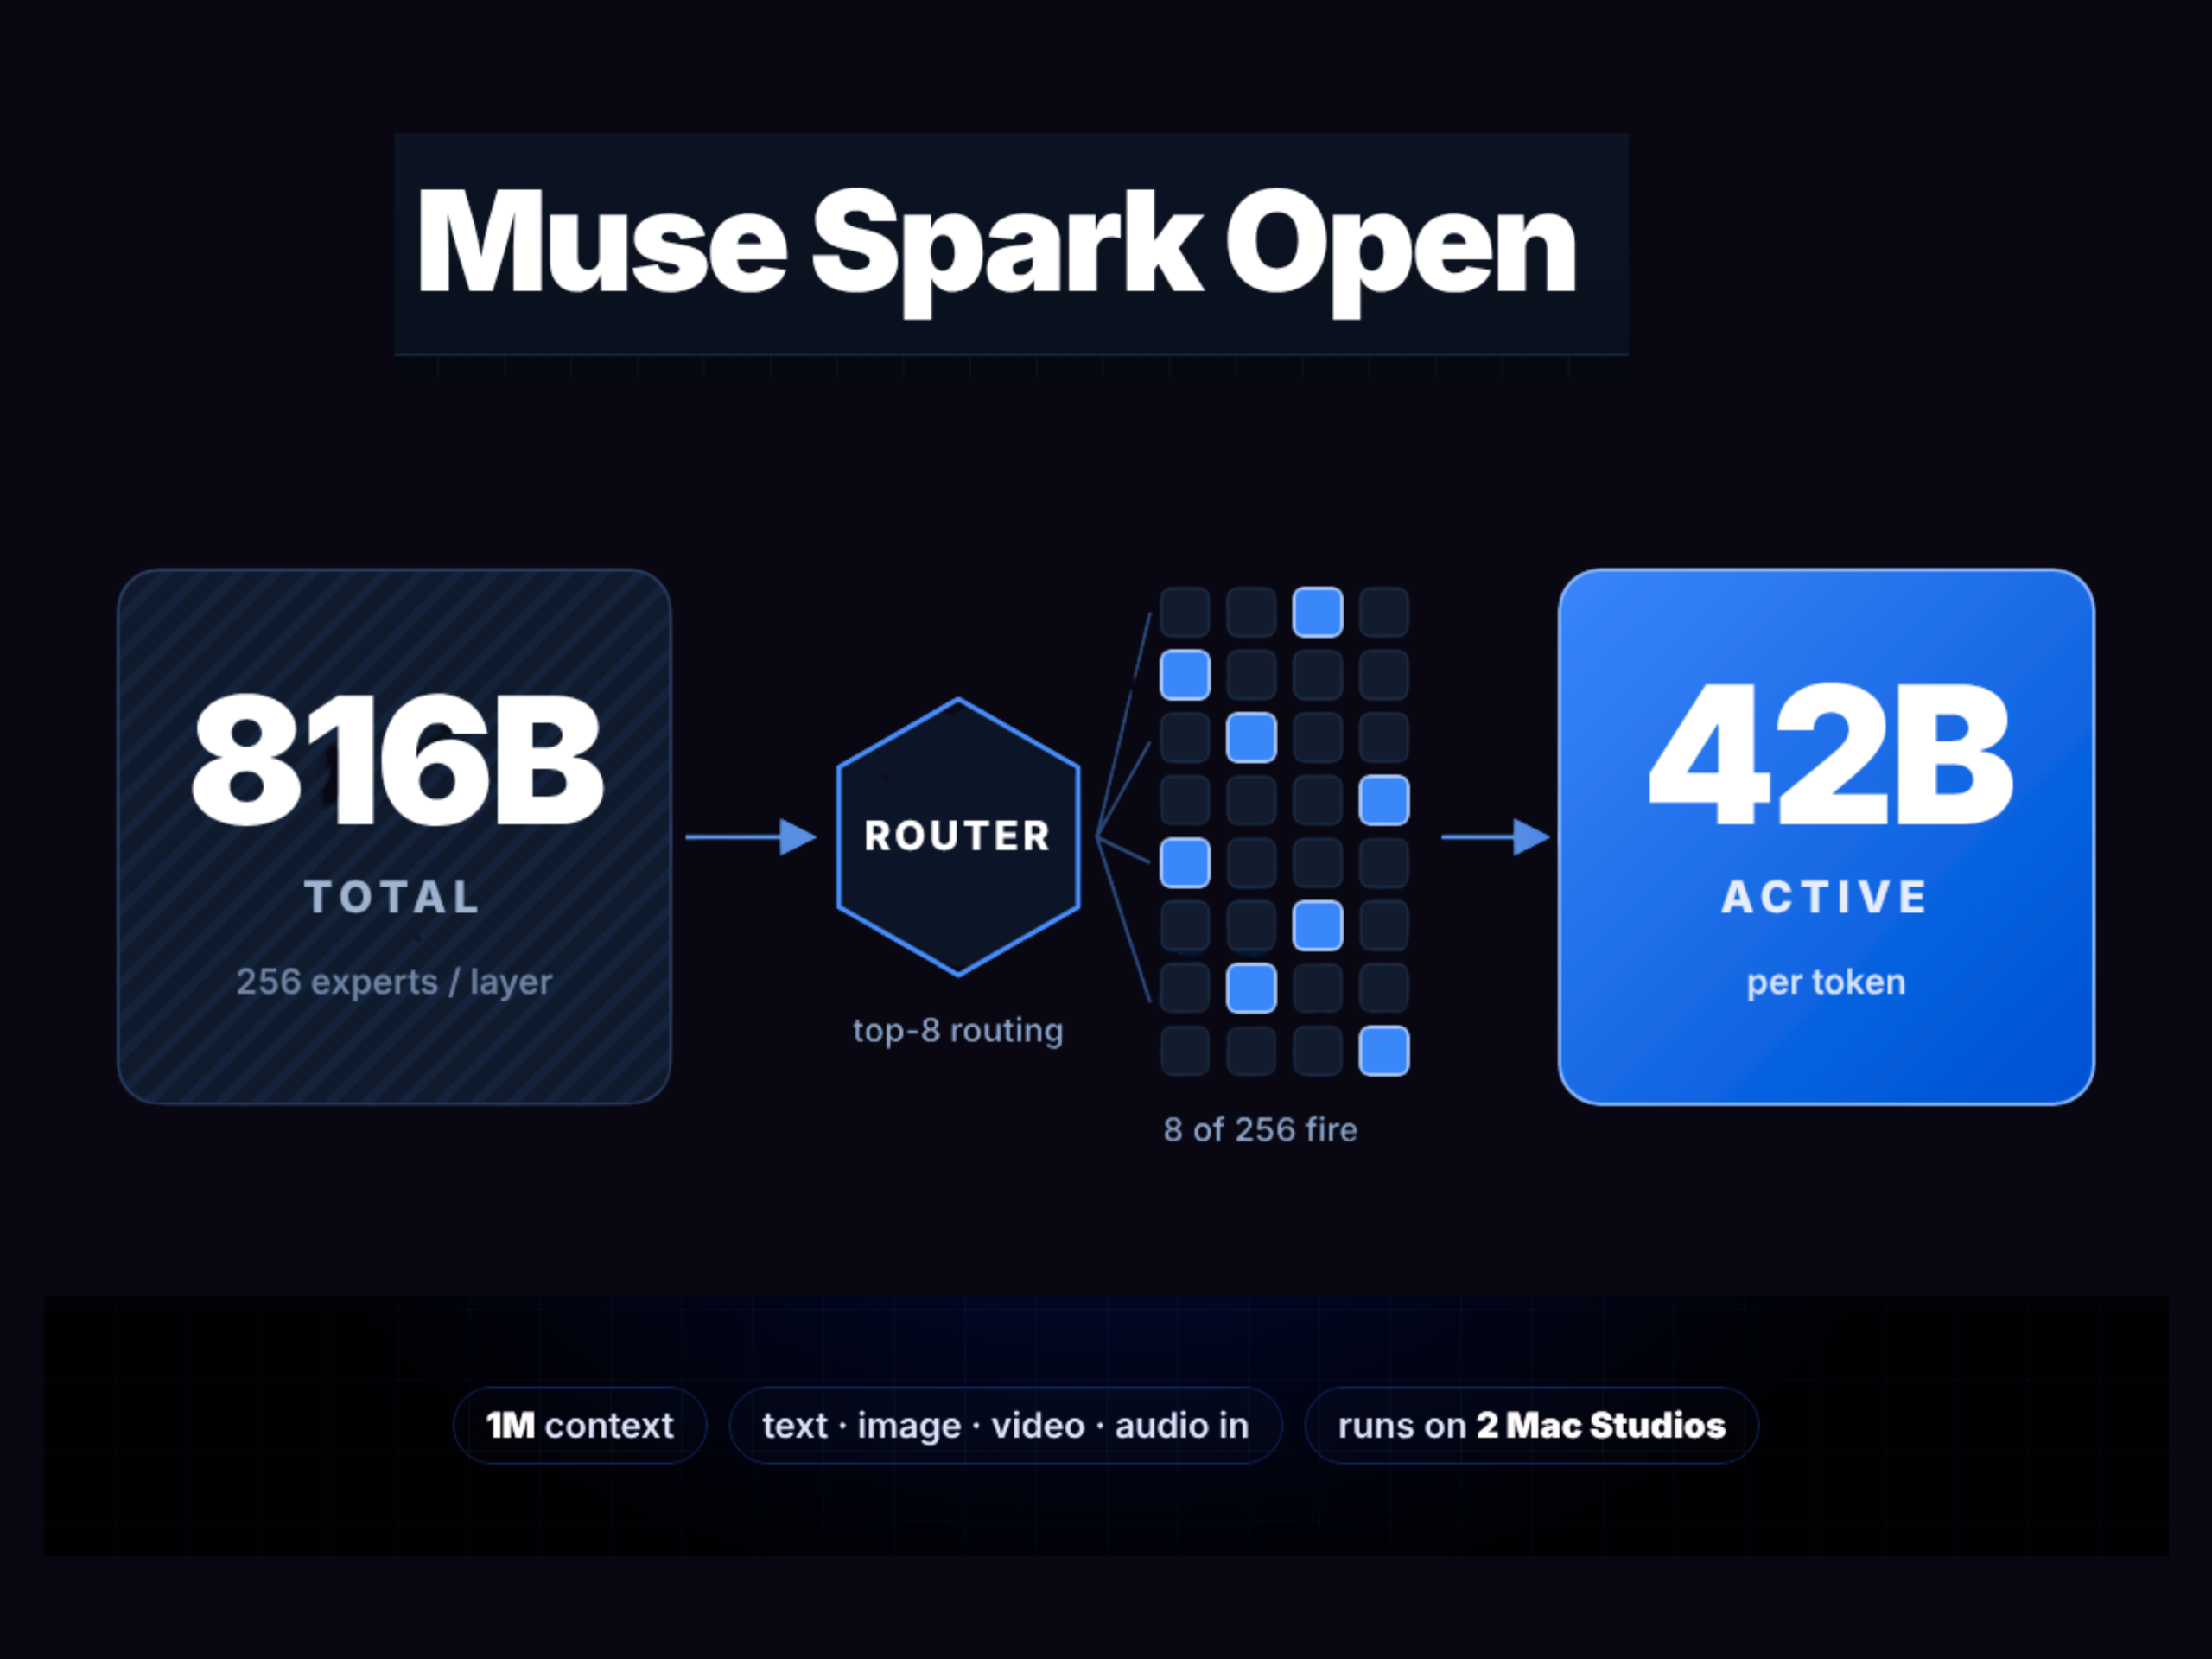
Meta Releases Muse Spark Open: 816B Open-Weight MoE With 1M Context
Meta released Muse Spark Open, an 816B-parameter open-weight MoE model with 42B active parameters and a 1M-token context. It leads open models on MCP-Atlas and runs on 2…

Discussion (0)
No comments yet. Start the conversation!