Architect Launches Liquid Inference, a Real-Time Auction for LLM Inference
Architect Financial Technologies has launched Liquid Inference, an LLM router that runs a live auction for every request. Liquid Inference is an LLM inference…
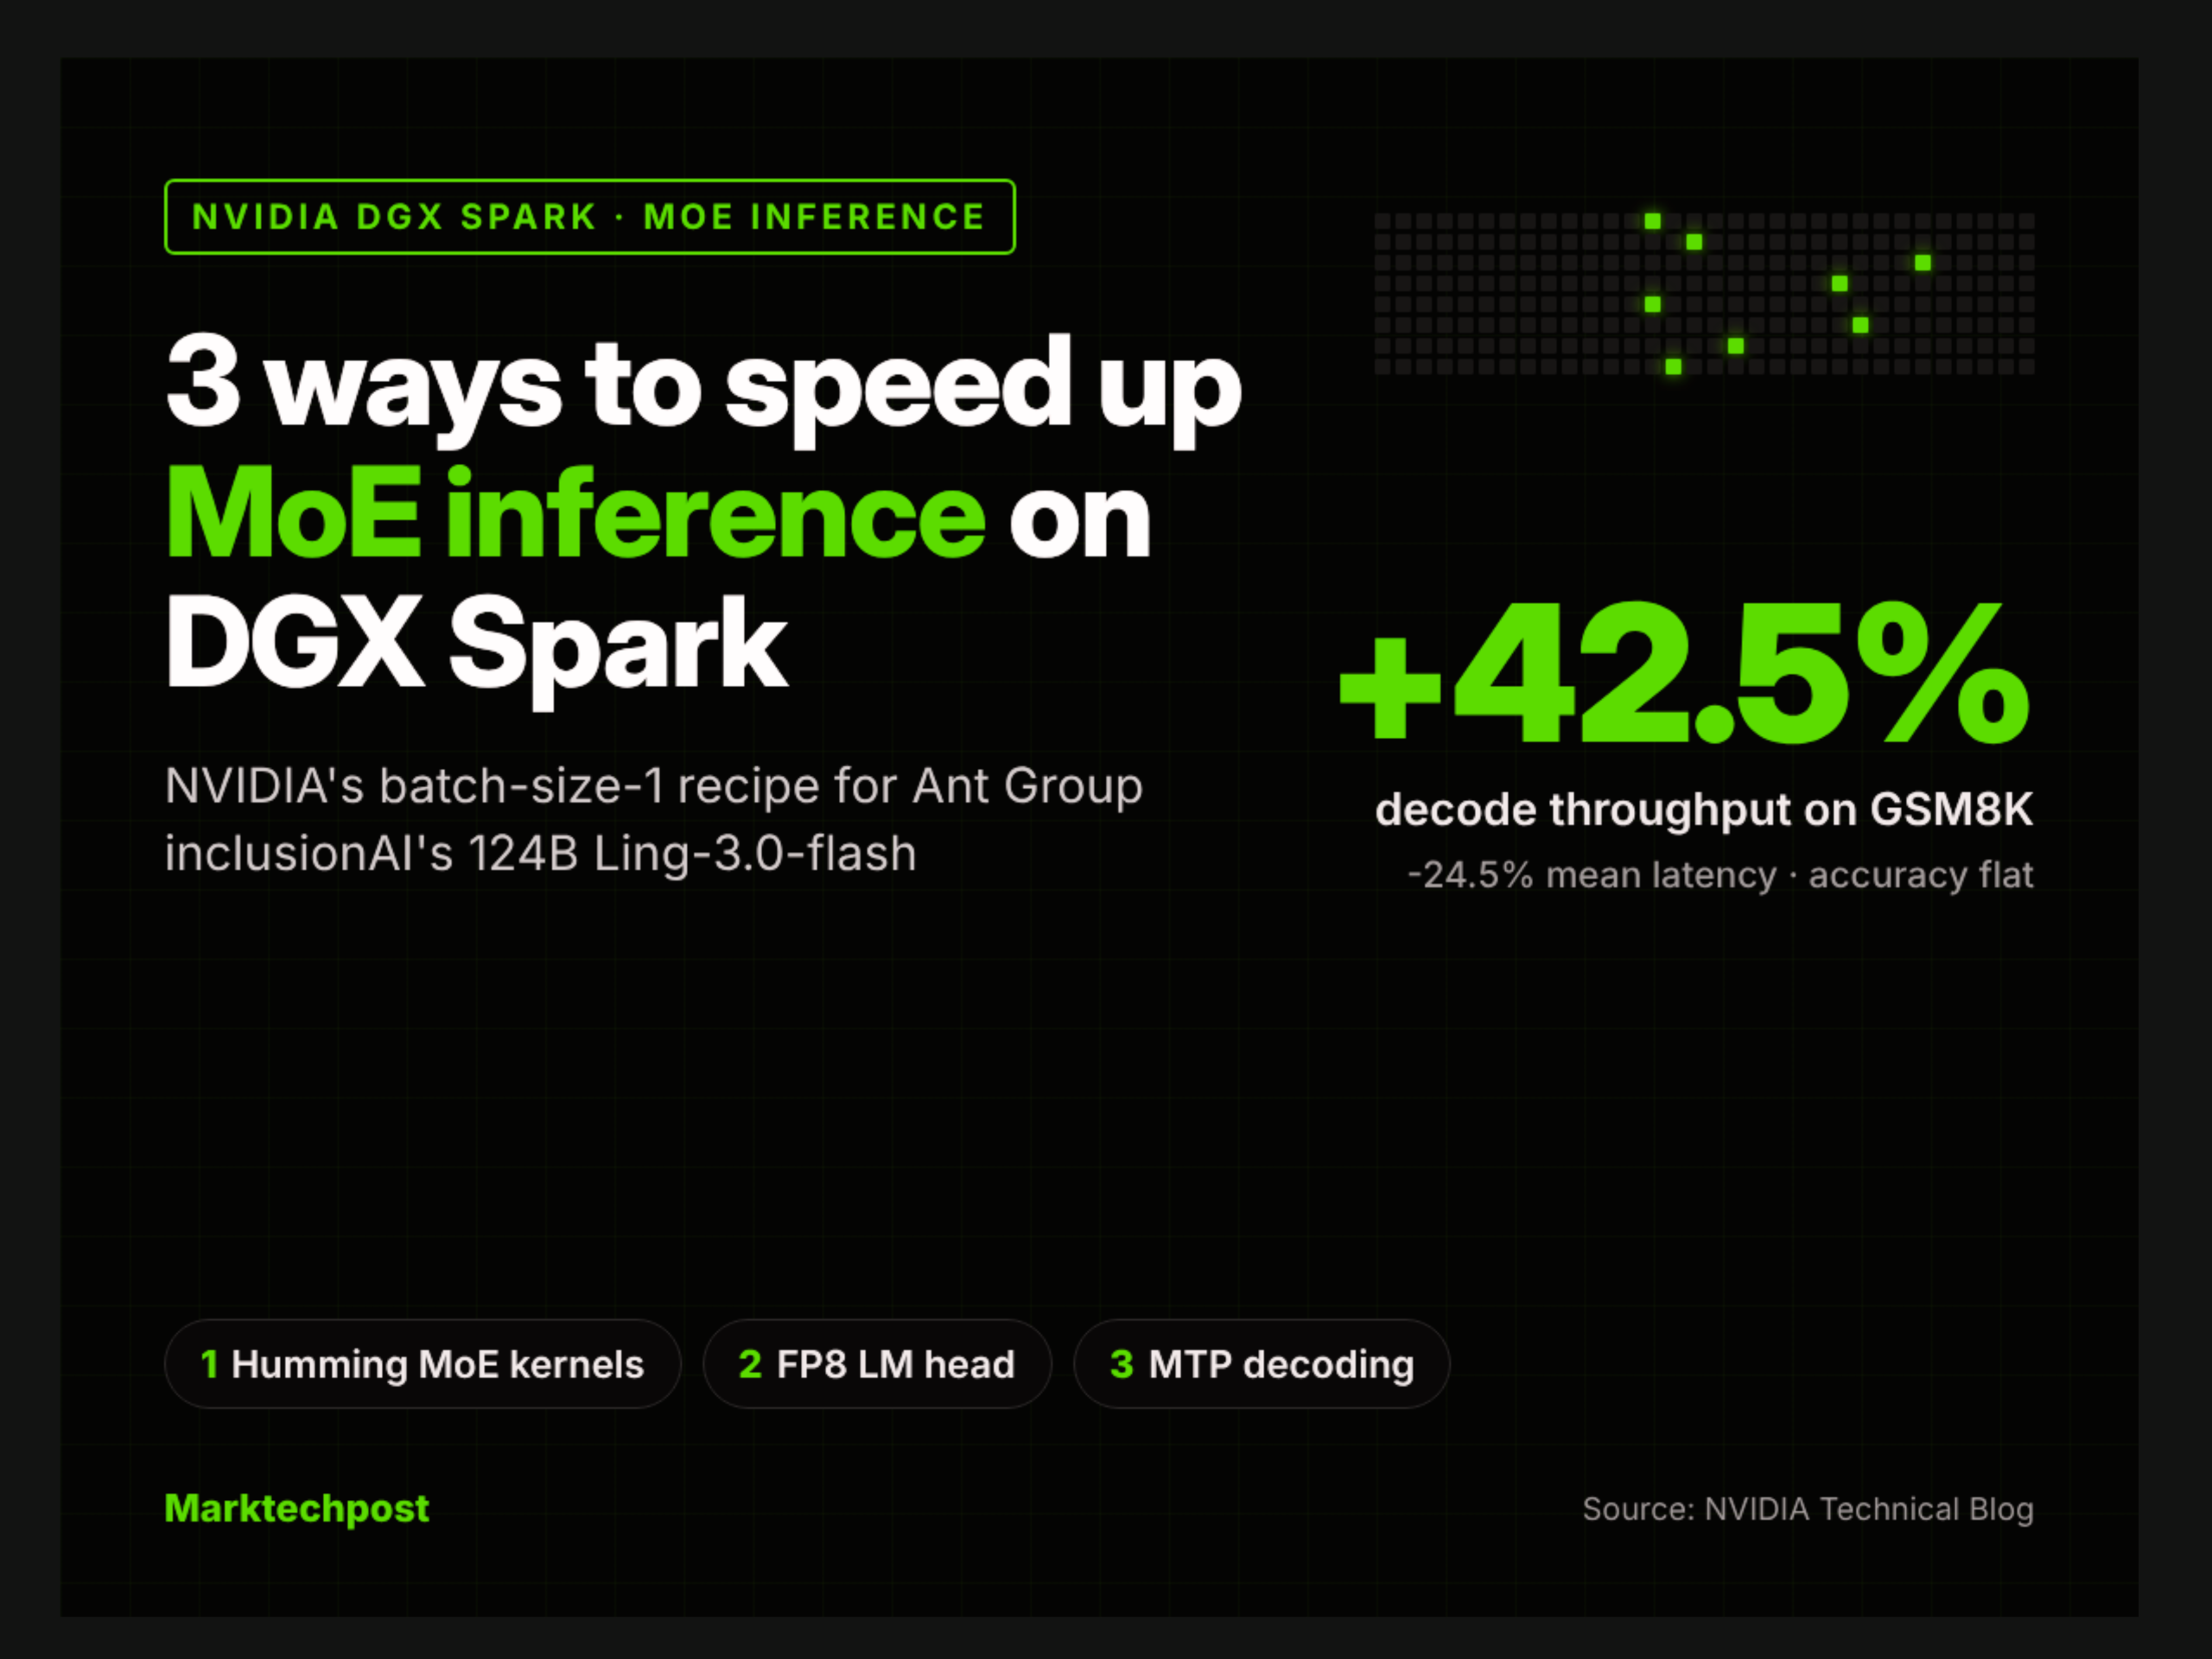
NVIDIA shows how 3 stacked optimizations speed up MoE inference on a single DGX Spark. On Ant Group inclusionAI's 124B Ling-3.0-flash, GSM8K decode throughput rose 42.5% with no detectable accuracy change.
The post NVIDIA Shows 3 Ways to Speed Up MoE Inference on DGX Spark, Lifting Ling-3.0-flash Throughput 42.5% appeared first on MarkTechPost.
Discussion (0)
No comments yet. Start the conversation!